Top AI sandbox platforms in 2026, ranked
An AI sandbox platform provides isolated environments for running AI-generated or other untrusted code. The best platforms combine fast startup, strong isolation, high concurrency, and support for the languages, tools, and workloads your agents need.
This guide compares six AI sandbox platforms for 2026:
- Northflank: Best overall for fast, high-concurrency sandboxes across coding agents, APIs, browser automation, and CPU or GPU workloads. Supports ephemeral and persistent environments, container images, and deployment on Northflank Cloud or in your own cloud.
- E2B: Best for teams prioritizing SDK-driven agent code execution.
- Modal: Best for Python-centric sandbox and machine learning workflows.
- Daytona: Best for programmable coding-agent workspaces.
- Together Code Sandbox: Best for teams using Together AI.
- Vercel Sandbox: Best for teams using Vercel’s sandbox tooling.
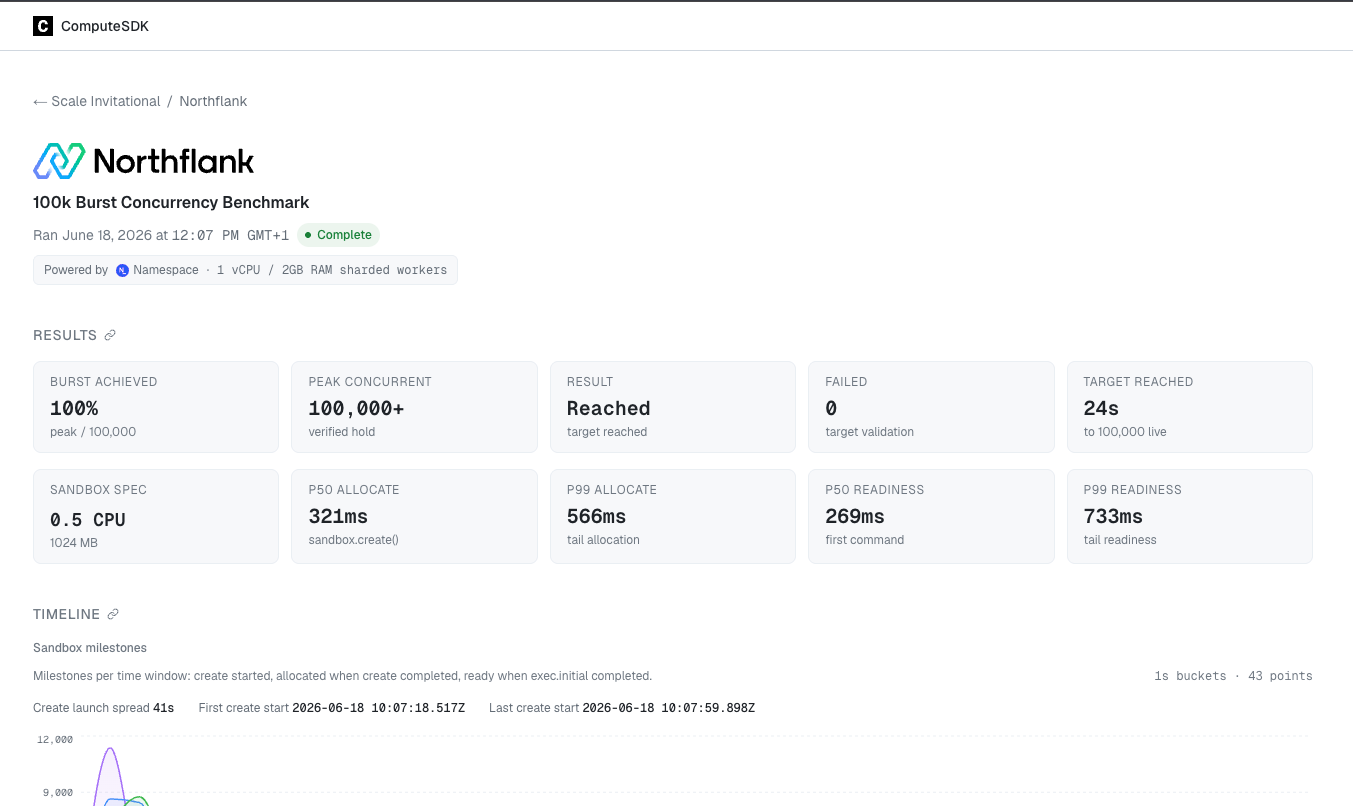
Northflank’s sandbox capabilities extend from individual agent tasks to large concurrent fleets. In the ComputeSDK 2026 Scale Invitational, Northflank reached 100,000 concurrent live sandboxes in 24 seconds from a cold start with zero failures.
Run a coding agent, execute generated scripts, start an isolated API, or provision separate environments for thousands of users. Northflank handles sandbox orchestration and scaling on managed infrastructure or inside your own cloud.
An AI sandbox platform creates and manages isolated environments where AI agents can execute code, install dependencies, work with files, and run tools without giving that code unrestricted access to the host or other workloads.
A sandbox can run more than a single code snippet. A coding agent might need a repository, a shell, a test runner, and a development server. A data analysis agent might execute Python against uploaded files. Another workload might need an isolated API, browser session, or GPU-enabled environment.
The platform manages provisioning, isolation, resource allocation, networking, persistence, and teardown. Your application still determines which credentials, data, and external systems each sandbox can access.
AI agents execute code that may not have been reviewed before it runs. Generated commands, unfamiliar dependencies, and untrusted repositories can introduce unexpected behavior into an otherwise legitimate workflow.
Sandboxing provides an execution boundary around that work. Network policies, scoped credentials, and resource limits help constrain what the code can reach and consume.
At scale, the challenge also becomes operational. A platform needs to start many environments at once, keep tenants isolated, and release resources when work finishes. Fast startup for one sandbox is useful; reliable startup across a large concurrent fleet supports production demand.
Compare platforms against the sandbox workloads you intend to run. Prioritize isolation, startup performance, concurrency, runtime compatibility, and lifecycle controls.
Sandbox runtimes use different security boundaries:
- Standard containers isolate processes but share the host kernel.
- gVisor intercepts application system calls through a user-space kernel, reducing direct exposure to the host kernel.
- MicroVM-based runtimes give workloads a separate guest kernel backed by hardware virtualization. Kata Containers can use a virtual machine monitor such as Cloud Hypervisor; Firecracker is another microVM technology.
Evaluate the runtime used for your actual workload and deployment target. Also check network restrictions, credential handling, and resource limits: the runtime boundary is one part of sandbox security.
Measure how long it takes from requesting a sandbox to successfully running your first command.
MicroVM boot time, sandbox allocation, application readiness, and snapshot resume measure different things. Compare equivalent measurements, using similar images, resources, and initialization steps.
For interactive agents, startup delays affect how quickly work begins. For batch execution, they affect how quickly you can launch the next group of tasks.
Check both how many sandboxes can run simultaneously and how quickly the platform can create them. Look for sustained concurrent capacity, creation throughput during bursts, failure rates under load, P95 and P99 readiness latency, and account quotas.
Monthly workload volume demonstrates usage, but it does not establish how many sandboxes can run concurrently. Evaluate those measures separately.
Check whether the sandbox can run your existing container image, language runtime, dependencies, and tools.
Useful workloads include coding agents, shell commands, browser automation, test suites, data processing, and API servers. For GPU workloads, verify hardware availability and the isolation model used.
Also check how your application executes commands, retrieves output, transfers files, and connects to services inside the sandbox.
Short tasks often suit disposable sandboxes. Coding agents and development workspaces may need files to survive across sessions.
Check maximum runtime, pause and resume behavior, storage retention, and cleanup controls. Persistent files do not necessarily mean that memory or running processes survive a pause.
Decide whether sandboxes should run on the provider’s managed infrastructure or inside your cloud account.
For BYOC deployments, verify supported infrastructure, runtime requirements, networking, and who manages sandbox orchestration. Assess the placement of workload data and control-plane services separately.
Northflank Sandboxes run untrusted code in isolated environments with sub-second boot times, support for large concurrent fleets, and flexible workload configuration. You can run a single coding-agent session or provision sandboxes for thousands of simultaneous users and tasks.
Use Northflank to sandbox a coding agent, run an API in isolation, execute generated Python or JavaScript, automate a browser, or run parallel tests. Environments can be ephemeral or use persistent storage, with CPU and GPU options available.
Northflank’s published results in the ComputeSDK 2026 Scale Invitational show:
- 100,000 concurrent live sandboxes reached from a cold start.
- 24 seconds to reach that fleet size.
- Zero failures in the benchmark run.
- 566ms P99 allocation latency.
- 733ms P99 readiness latency.
These results demonstrate sandbox creation under a large burst of demand. Actual readiness depends on the image, resources, initialization work, and infrastructure used.
Northflank supports container-based sandbox environments for different execution patterns:
- Coding agents: Clone repositories, install dependencies, edit files, and run tests inside an isolated workspace.
- APIs and development servers: Run a service inside the sandbox and expose the ports needed to interact with it.
- Code execution: Execute generated scripts, shell commands, and user-submitted code.
- Browser automation: Give browser agents separate environments for their tools and dependencies.
- Parallel evaluation and testing: Create isolated environments for independent tasks and test runs.
- GPU workloads: Run supported GPU-enabled workloads with sandbox isolation appropriate to the infrastructure.
On Northflank Cloud, CPU sandboxes use microVM isolation and GPU sandboxes use gVisor. Isolation is applied automatically.
For sandboxes in your own cloud, configure the runtime and infrastructure for your workload. MicroVM availability depends on hardware and virtualization support.
Bring a container image with the languages, packages, and tools your workload requires. Create and manage environments programmatically, execute commands, collect results, and destroy sandboxes when work finishes.
Use ephemeral storage for disposable execution or attach persistent volumes when files need to survive restarts and pauses. Northflank supports long-running sandbox workloads without a fixed session-duration cap.
Start on Northflank’s managed infrastructure or deploy sandbox workloads into your own cloud account through BYOC. Northflank manages orchestration, allowing your team to focus on how agents use the environments.
cto.new uses Northflank’s sandbox infrastructure for its code-generation workflows. During its launch to more than 30,000 users, Northflank supported thousands of daily deployments.
Teams that need fast sandbox startup, high concurrency, isolated coding-agent workspaces, and support for workloads ranging from generated scripts to APIs and GPU-enabled execution.
Get started with Northflank, or talk to an engineer about sandbox capacity, isolation, or deployment requirements.
E2B built its sandbox platform specifically for AI agent developers, offering polished Python and JavaScript SDKs for programmatic code execution.
- Firecracker microVM isolation: Each sandbox in this AI code execution product runs in a dedicated lightweight VM
- 150ms cold starts: Fast environment provisioning for responsive AI sandbox runners
- Session persistence: Pause and resume sandboxes from saved state
- 24-hour session cap: Even Pro plans limit this sandbox product to day-long sessions
- Self-hosting complexity: Scaling the AI sandbox platform past hundreds of concurrent environments requires operating E2B's control plane
- No network policies: Lacks granular egress controls for AI code execution
- Docker image requirements: Custom environments require building and pushing images
- Hobby: Free with $100 credit, 1-hour sessions, 20 concurrent sandboxes
- Pro: $150/month, 24-hour sessions, configurable resources
- Usage: ~$0.05/hour per 1 vCPU sandbox
Modal provides a serverless compute platform optimized for machine learning, with AI sandbox capabilities integrated into a broader Python-centric infrastructure.
- Massive autoscaling: This sandbox runner scales from zero to 20,000+ concurrent containers with sub-second cold starts
- Python-first experience: Define AI sandbox environments in Python code
- Built-in networking: Tunneling and egress policies for code execution platform connectivity
- Snapshot primitives: Save and restore sandbox state efficiently
- GPU access: Full range of NVIDIA GPUs for ML workloads
- No BYOC: This AI sandbox platform offers managed deployment only, no option to run in your cloud
- SDK-defined images: Cannot bring arbitrary OCI containers to this sandbox product
- Python-centric: JavaScript and Go SDKs exist but the code execution platform optimizes for Python
- gVisor only: No microVM option for stronger isolation in this AI sandbox runner
- CPU: $0.047/vCPU-hour
- RAM: $0.008/GB-hour
- H100 GPU: $3.95/hour (plus CPU and RAM charges)
- $30/month free credits
cto.new uses Northflank’s microVMs to scale secure sandboxes without sacrificing speed or cost. Read more about their use case running Northflank secure sandboxes here.
Daytona pivoted in early 2025 from development environments to AI agent infrastructure, providing programmable sandbox environments for code execution.
- Fast provisioning: Designed for responsive coding-agent workflows; compare startup measurements under equivalent workload conditions
- Docker compatibility: Standard container workflows function without proprietary formats on this sandbox platform
- Stateful execution: Filesystem, environment variables, and process memory persist across interactions
- Docker isolation default: This AI sandbox product uses standard containers by default—weaker than microVMs. Kata Containers available but not default.
- Maturing platform: Feature parity with established sandbox platforms still developing
- Limited networking: No first-class tunneling or egress policies in this code execution platform
- $200 free compute credit
- Pay-per-use after credits
- Startup program: up to $50k credits
Together AI extended their GPU cloud with sandbox platform capabilities, providing integrated code execution for teams already using Together's inference infrastructure.
- 500ms snapshot resume: This AI sandbox product resumes VMs from snapshot with memory pre-loaded
- Hot-swappable sizing: Scale from 2 to 64 vCPUs dynamically on this code execution platform
- Together AI integration: Seamless connection between model inference and sandbox execution
- Slower cold starts: 2.7 seconds for fresh sandbox creation versus sub-second competitors
- VM-style pricing: Per vCPU and GB-RAM billing less attractive for bursty AI code execution
- No tunneling: Lacks network tunneling features found in other sandbox platforms
- Dev container format: Must use Docker-based dev container images for this AI sandbox runner
- ~$0.089/vCPU-hour
- Billed per vCPU and GB-RAM per minute
Vercel launched their sandbox platform in beta, offering Firecracker-based isolation tightly coupled with Vercel's deployment infrastructure.
- Firecracker microVMs: True VM-level isolation for this AI code execution product
- Vercel integration: Seamless experience for teams using Vercel's platform
- Active CPU billing: Charges only when code actively executes in the sandbox runner
- Strict time limits: 45 minutes (Hobby) to 5 hours (Pro/Enterprise) maximum for this AI sandbox platform
- Limited runtimes: Only Node.js and Python supported in this sandbox product
- Single region: Only iad1 available for this AI code execution platform
- Vercel dependency: Designed for Vercel ecosystem—limited standalone utility as a sandbox runner
- Beta status: Production readiness timeline unclear for this AI sandbox product
- Hobby: 5 CPU hours, 420 GB-hours memory, 5,000 sandbox creations free
- Pro: $0.128/CPU-hour, $0.0106/GB-hour memory, $0.60/million creations
Northflank pricing
Transparent usage-based pricing:
- CPU: $0.01667/vCPU-hour
- RAM: $0.00833/GB-hour
- GPU (H100): $2.74/hour all-inclusive
To make the pricing difference concrete, here is what 200 sandboxes cost across providers under the same conditions.
Based on 200 sandboxes, plan: nf-compute-100-4, infra node: m7i.2xlarge
| Model | Provider | Cloud | Sandbox vendor | Total |
|---|---|---|---|---|
| PaaS | Northflank | — | $7,200.00 | $7,200.00 |
| PaaS | E2B | — | $16,819.20 | $16,819.20 |
| PaaS | Modal | — | $24,491.50 | $24,491.50 |
| PaaS | Vercel Sandbox | — | $31,068.80 | $31,068.80 |
| BYOC (0.2 overcommit)* | Northflank | $1,500.00 | $560.00 | $2,060.00 |
| BYOC | E2B | $1,500.00 | $10,000.00 | $11,500.00 |
*Through Northflank's plans on BYOC, there's a default overcommit which allows a customer to spawn more services and sandboxes on the same amount of compute. A request modifier of 0.2 means each sandbox only requests 20% of its plan's resources as a guaranteed minimum, but can burst up to the full plan limit if there's available capacity on the node. So instead of fitting 8 sandboxes per node, you could fit 40 on the same hardware, reducing both infrastructure cost and the Northflank management fee.
Northflank's GPU pricing includes CPU and RAM, approximately 62% cheaper than comparable AI sandbox products charging separately.
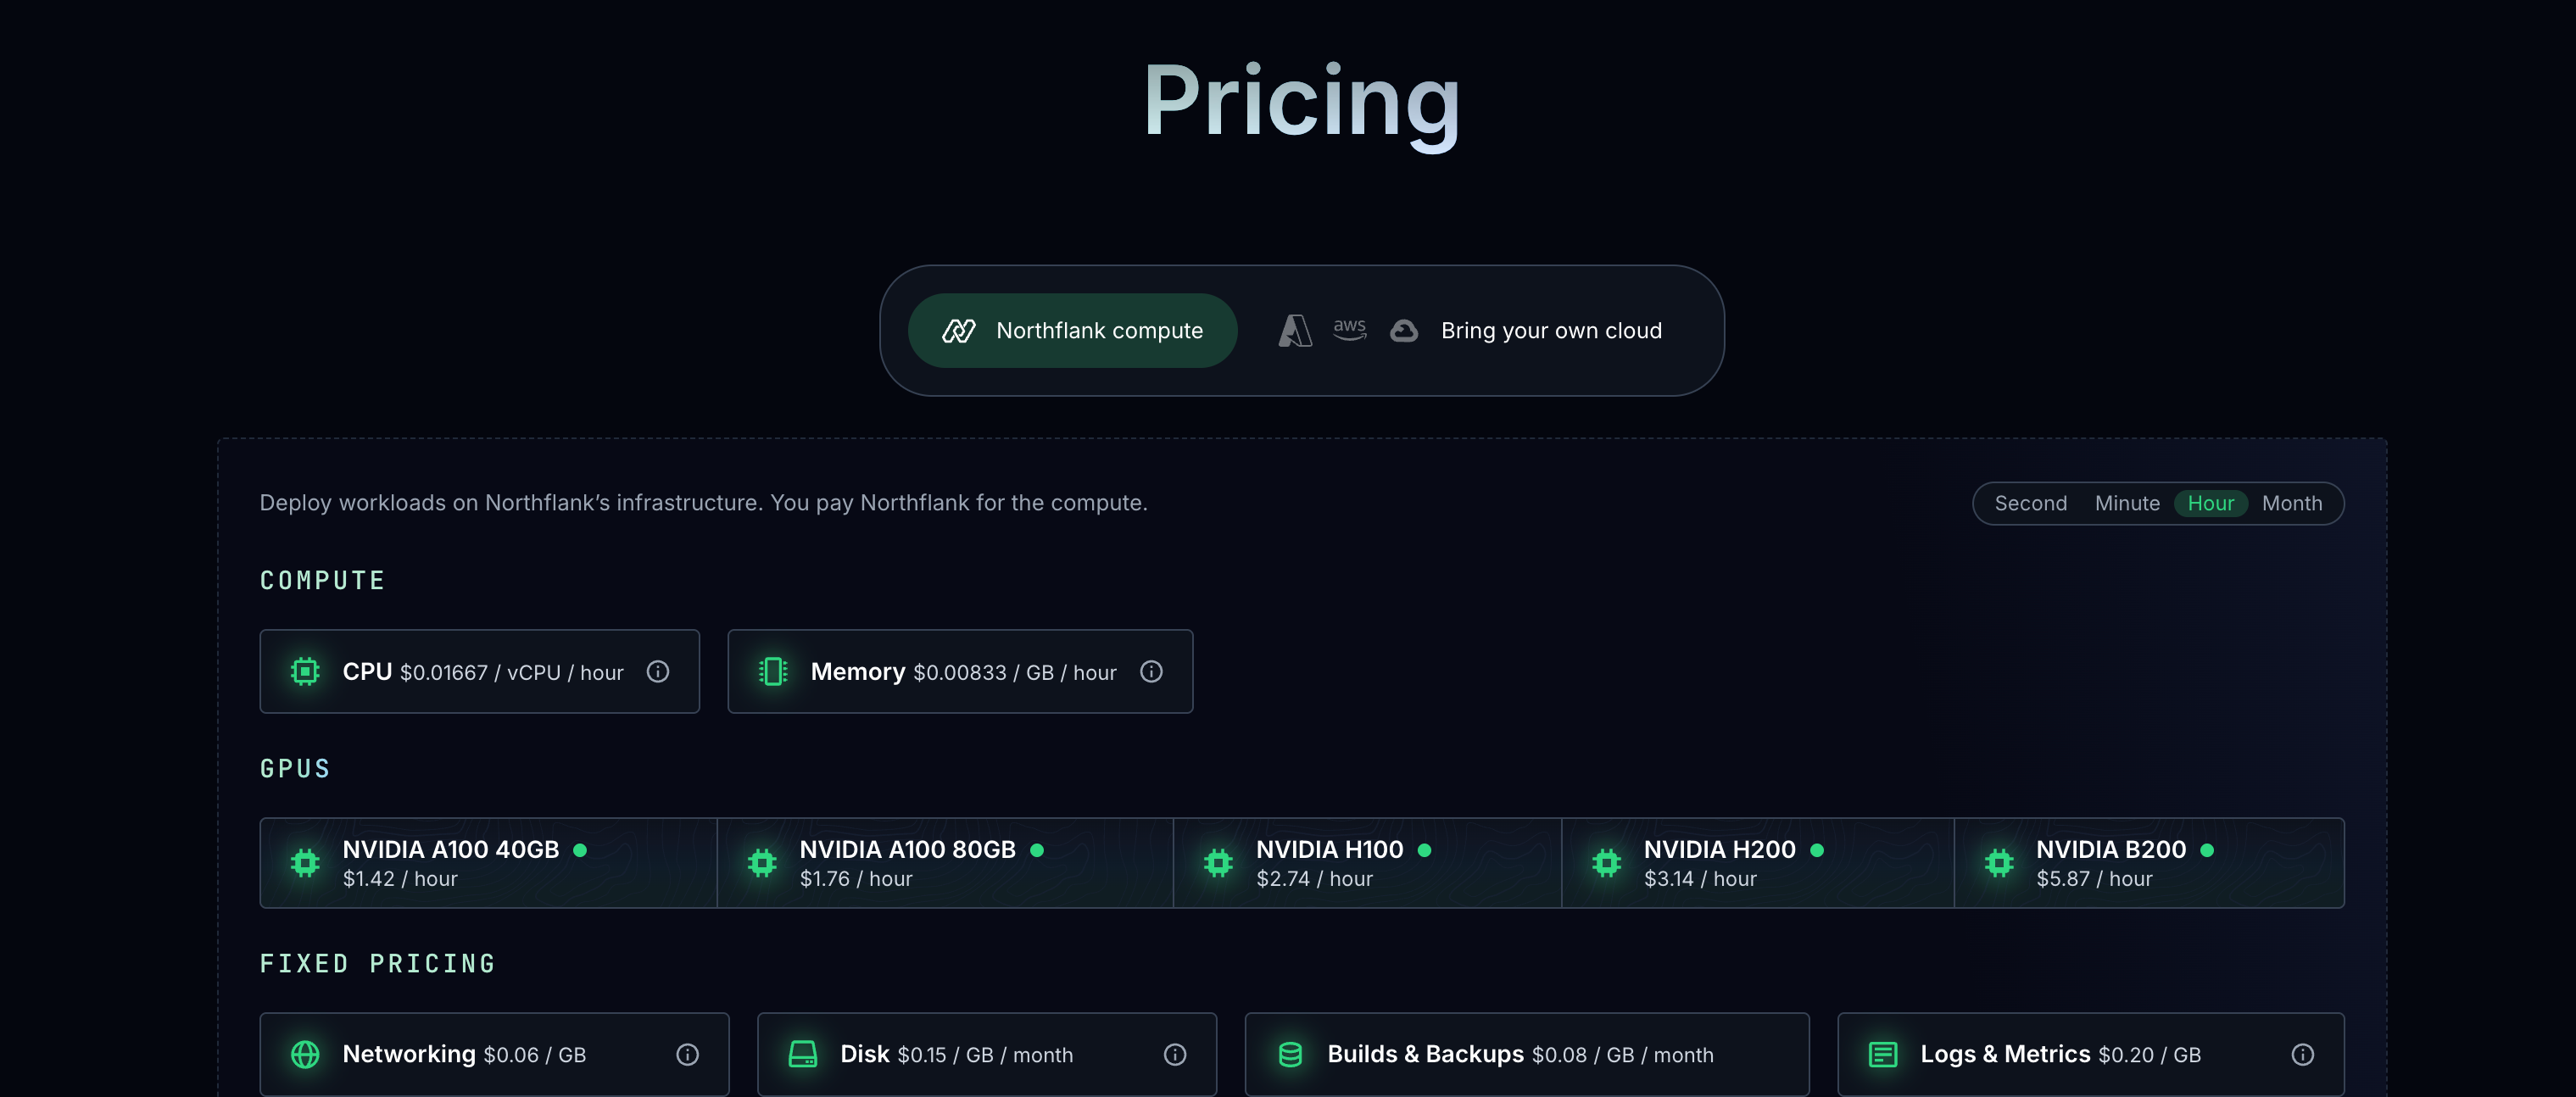
Pricing as of April 2026. Billing models differ across platforms (some bill based on active CPU usage only, others bill for the entire duration the sandbox is running). Verify current rates on each platform's pricing page before making cost decisions.
| Platform | CPU | Memory | Storage | GPU | Billing model |
|---|---|---|---|---|---|
| Northflank | $0.01667/vCPU-hr | $0.00833/GB-hr | $0.15/GB-month | L4: $0.80/hr, A100 40GB: $1.42/hr, A100 80GB: $1.76/hr, H100: $2.74/hr, H200: $3.14/hr | Per second |
| E2B | $0.0504/vCPU-hr | $0.0162/GiB-hr | 10–20GB included free | Do not provide GPU compute | Per second |
| Daytona | $0.0504/vCPU-hr | $0.0162/GiB-hr | $0.000108/GiB-hr (5GB free) | Do not provide GPU compute | Per second |
| Vercel Sandbox | $0.128/vCPU-hr | $0.0212/GB-hr | $0.023/GB-month (snapshots) | Do not provide GPU compute | Active CPU only |
| Modal Sandboxes | $0.1419/physical core-hr (2 vCPU) | $0.0242/GiB-hr | — | L4: $0.80/hr, A100 40GB: $2.10/hr, A100 80GB: $2.50/hr, H100: $3.95/hr, H200: $4.54/hr | Per second |
The table below shows how each platform handles BYOC deployment, which clouds are supported, and whether it requires a sales process.
| Platform | BYOC available | Clouds supported | Access model | Pricing model |
|---|---|---|---|---|
| Northflank | Yes, fully self-serve | AWS, GCP, Azure, Oracle, CoreWeave, any neoclouds, Civo, bare-metal, on-premises | Self-serve, enterprise contracts available for larger commits (with bulk discounts) | Your existing cloud bill, CPU $0.01389/vCPU-hr and Memory $0.00139/GB-hr |
| E2B | Yes, limited and not self-serve | AWS and GCP only | Not publicly disclosed, need to contact sales | Starts at $50/sandbox/month, on top of your existing cloud bill |
| Daytona | Yes, limited and not self-serve | Not publicly disclosed | You operate the infrastructure layer; Daytona provides the control plane | Not publicly disclosed |
| Modal | No | Managed only | — | — |
| Vercel Sandbox | No | Managed only (iad1 region only) | — | — |
| Together Code Sandbox | No | Managed only | — | — |
Choose Northflank if:
- You need fast sandbox startup and high concurrency.
- You want to sandbox coding agents, APIs, browser tools, or other container-based workloads.
- You need ephemeral execution or persistent workspaces without a fixed session-duration cap.
- You need CPU or GPU sandboxes.
- You want managed sandbox infrastructure or deployment in your own cloud.
Choose E2B if:
- SDK quality is your top priority for AI code execution
- 24-hour sessions are sufficient
- You prefer open-source foundations in your sandbox product
Choose Modal if:
- Your team is Python-focused for ML workloads
- You need massive autoscaling in an AI sandbox runner
- gVisor isolation meets your security requirements
Choose Daytona if:
- Cold start speed is the critical factor for your sandbox platform
- Docker-level isolation is acceptable for your AI code execution needs
- You're running high-volume, short-duration agent workflows
Choose Together if:
- You already use Together AI for model inference
- Integrated AI sandbox and inference simplifies your architecture
Choose Vercel if:
- You're deeply invested in Vercel's ecosystem
- Short session limits (under 5 hours) work for your sandbox product needs
To start using the leading AI sandbox platform:
- Sign up at northflank.com
- Create a project, select your region or connect your cloud account for BYOC
- Deploy a service, choose any container image from any registry
- Configure isolation, Northflank provisions microVM-backed infrastructure automatically
For enterprise requirements, schedule a demo with Northflank's engineering team to discuss custom AI sandbox platform configurations, compliance needs, or volume pricing.
An AI sandbox platform is infrastructure providing isolated environments for executing code generated by AI systems. These sandbox products prevent untrusted AI-generated code from accessing production resources, leaking data, or compromising host systems. The platform handles provisioning, isolation, networking, and teardown of code execution environments.
Sandbox platforms using microVMs (Firecracker, Kata Containers) provide stronger isolation than container-based solutions because each workload receives a dedicated kernel. Northflank offers both Kata Containers and gVisor, making it the most flexible AI sandbox platform for security requirements. E2B and Vercel also use Firecracker microVMs.
Many AI sandbox products impose time limits: Vercel caps at 5 hours, E2B at 24 hours. For AI agents maintaining state across extended interactions, these limits require complex state serialization. Northflank's sandbox platform offers unlimited sessions, avoiding this architectural overhead.
BYOC (Bring Your Own Cloud) means the sandbox platform vendor manages the control plane while provisioning resources in your cloud account, you get managed operations with data in your VPC. Self-hosting means operating everything yourself. Northflank offers production-ready BYOC; E2B's self-hosting remains experimental.
Pricing varies by workload pattern. For CPU-intensive AI code execution, Northflank ($0.01667/vCPU-hour) costs approximately 65% less than Modal ($0.047/vCPU-hour). For GPU workloads, Northflank's all-inclusive pricing ($2.74/hour for H100) runs approximately 62% cheaper than sandbox products billing GPU, CPU, and RAM separately.
Some AI sandbox products support GPU-accelerated code execution. Northflank offers NVIDIA H100, A100, and other GPUs with all-inclusive pricing. Modal also provides GPU access but charges separately for GPU, CPU, and RAM. Verify your sandbox platform supports required GPU types before committing.